Async-RBench
Benchmarking Asynchronous Task Execution in LLM Agents
Async-RBench evaluates how agents adapt ongoing work as new results arrive.评测智能体在新结果陆续到达时,如何调整正在执行的任务。
Abstract
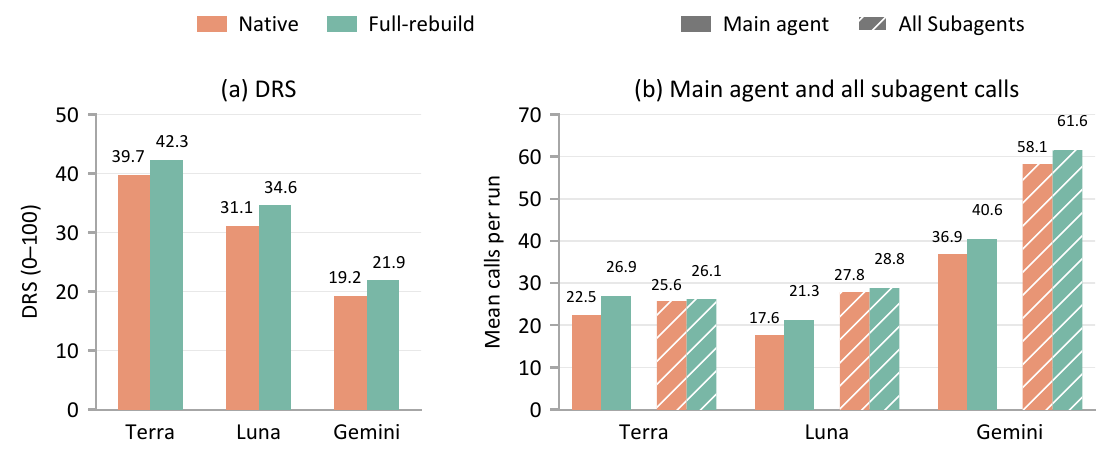
Large language model (LLM) agents increasingly execute tasks asynchronously: a main agent continues working while its subagents run, and the task state may change before their results arrive. The main agent must decide which work to update or preserve and which checks to repeat, while avoiding prohibited changes. Final task success alone does not reveal whether these results were handled correctly, and natural asynchronous arrivals are hard to reproduce. We introduce Async-RBench, a benchmark for asynchronous task execution in LLM agents, with 200 executable tasks covering eight scenarios. A scenario controller regulates result delivery using predefined task-state conditions, while an Event Response Contract (ERC) specifies what each response must change, preserve, avoid, and re-verify. The Dynamic Replanning Score (DRS) weights the response process and outcome equally and is reported separately from task success. We evaluate nine agents and find DRS scores of 19.2–45.1, with the lowest scores on duplicate reports and subagent failures. Under our execution protocol, all nine agents obtain lower task success with asynchronous than with batched delivery (26.0% vs. 29.7% on average). For three agents, prompting the main agent to rebuild its plan after every result improves DRS by only 2.6–3.5 points. Together, these findings highlight the challenges of reliable asynchronous task execution and the need to evaluate how agents handle incoming results alongside end-to-end task success.
Evaluation framework评测框架

About the framework框架说明
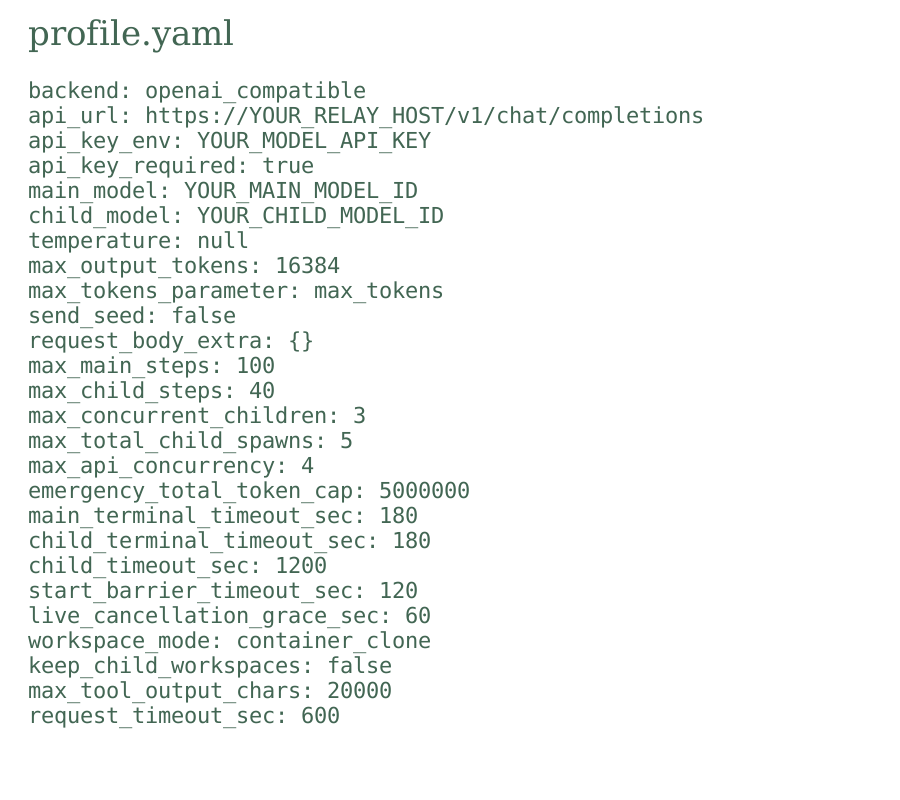
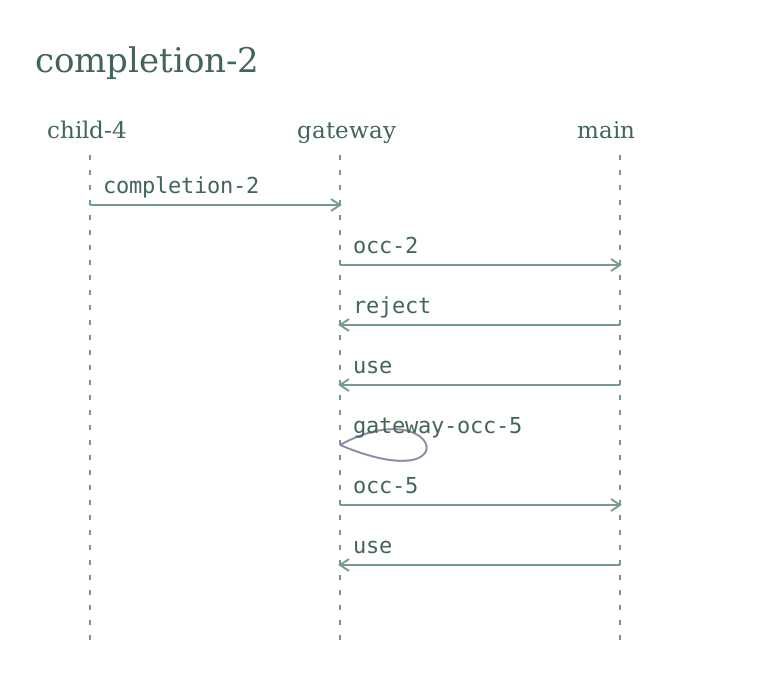
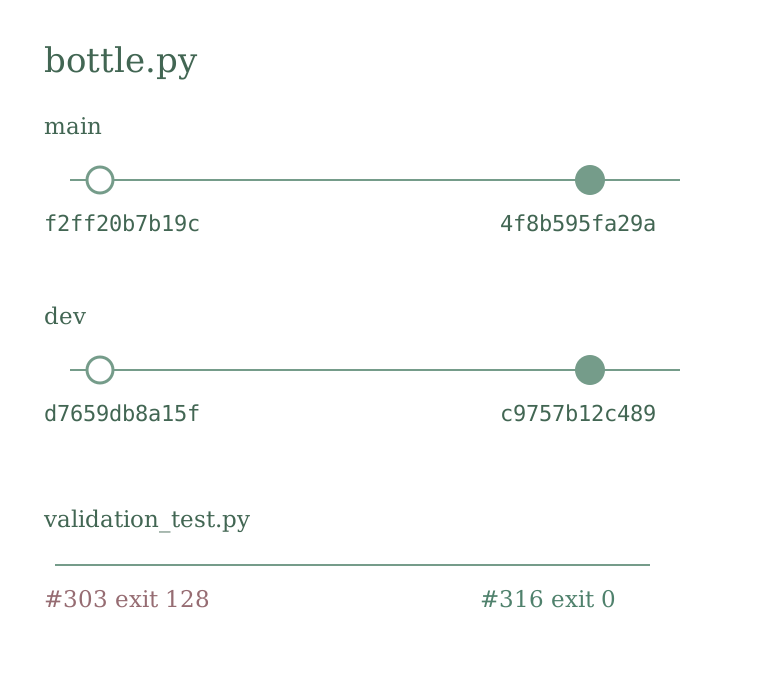
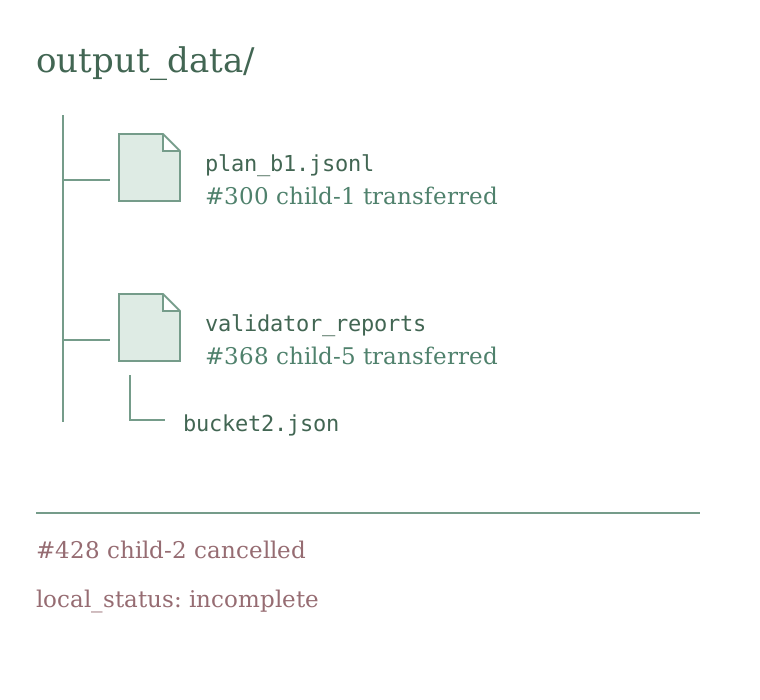
The configuration sets the model, task and execution limits. The main agent delegates parallel work to subagents in isolated workspaces and continues working while they run. A scenario controller releases their results under predefined conditions. The main agent must then update affected work, preserve valid progress and verify its changes. The runtime records actions and artifact states. An external evaluator checks this evidence against a private Event Response Contract (ERC), reporting the Dynamic Replanning Score (DRS) separately from final task success.配置指定模型、任务和运行限制。主代理将并行工作分派给隔离工作区中的子代理,并在它们运行时继续执行任务。场景控制器按预设条件交付结果;主代理需要据此修改受影响的工作、保留有效进展并验证修改。运行框架记录动作和产物状态,外部评估器依据私有的事件响应契约(Event Response Contract,ERC)检查这些证据,分别报告动态重规划分数(Dynamic Replanning Score,DRS)和最终任务成功情况。
Tasks任务
- Medium中等
- 104 · 52%
- Hard困难
- 96 · 48%
Scenario distribution场景分布
Tasks任务数- Delayed authoritative result权威结果延迟
- 25
- Superseded result arriving late or out of order已被替代的结果迟到或乱序到达
- 25
- Conflicting valid-looking results表面有效的结果相互冲突
- 25
- Duplicate or replayed completion完成结果重复或重放
- 25
- Partial, then complete result部分结果后续补全
- 25
- Subagent failure or implicit error子代理失败或隐性错误
- 25
- Change in task scope or dependencies任务范围或依赖变化
- 25
- Straggler under resource pressure资源压力下的慢任务
- 25
Leaderboard榜单
The paper evaluates nine agents on the same 200 tasks, with three repetitions per task for both asynchronous (Async) and batched (Batched) result delivery. DRS measures an agent’s ability to replan under asynchronous interruptions, accounting for both the response process and the event outcome. S is the end-to-end task success rate. Higher is better for both.论文在相同的 200 个任务上评测九个智能体,分别采用异步(Async)和批量(Batched)结果交付,每个任务各重复三次。DRS 衡量智能体在异步中断下的动态重规划能力,综合考察响应过程及事件结果;S 是端到端任务成功率,两者均越高越好。
| # | Agent | DRS | S · Async % | S · Batched % | ΔS · pp | Calls |
|---|---|---|---|---|---|---|
| 01 | Claude Sonnet 5 | 45.1 | 38.2 | 42.3 | -4.2 | 77.1 |
| ||||||
| 02 | GPT-5.6 Terra | 39.7 | 38.8 | 41.3 | -2.5 | 48.1 |
| ||||||
| 03 | Qwen3.7 Plus | 38.2 | 18.7 | 21.3 | -2.7 | 75.9 |
| ||||||
| 04 | GLM5.3 Flash | 33.4 | 20.8 | 25.5 | -4.7 | 76.5 |
| ||||||
| 05 | GPT-5.6 Luna | 31.1 | 34.3 | 40.2 | -5.8 | 45.5 |
| ||||||
| 06 | DeepSeek V4 Pro | 30.6 | 34.7 | 35.7 | -1.0 | 108.0 |
| ||||||
| 07 | Qwen3.5 27B | 29.8 | 17.0 | 19.7 | -2.7 | 119.6 |
| ||||||
| 08 | Kimi K2.5 | 26.1 | 19.2 | 23.2 | -4.0 | 125.2 |
| ||||||
| 09 | Gemini 3 Flash High | 19.2 | 12.3 | 18.3 | -6.0 | 95.0 |
| ||||||
The eight scores below each agent are scenario-level DRS values, not additional metrics. For each scenario, we average its 25 task scores within each repetition, then report the mean ± sample standard deviation across the three repetitions. Overall DRS is the equal-weight mean of the eight scenario means.每个智能体下方的八项分数是八类场景各自的 DRS,而非额外指标。每类场景先在每次重复内对 25 个任务的分数求均值,再报告三次重复的均值 ± 样本标准差。总 DRS 是八类场景均值的等权平均。
ΔS is the Async task success rate minus the Batched task success rate, in percentage points (pp), calculated before rounding. Calls is the mean number of model responses per Async run, summed over the main agent and all subagents. These values come from the paper; community submissions do not change this table.ΔS 是 Async 任务成功率减去 Batched 任务成功率,单位为百分点(pp),在四舍五入前计算。Calls 先合计每次 Async 运行中主代理和所有子代理的模型响应次数,再对运行取平均。数值来自论文,社区提交不会改变此表。
Scoring and aggregation details ↗评分与汇总细则 ↗Additional experiments补充实验
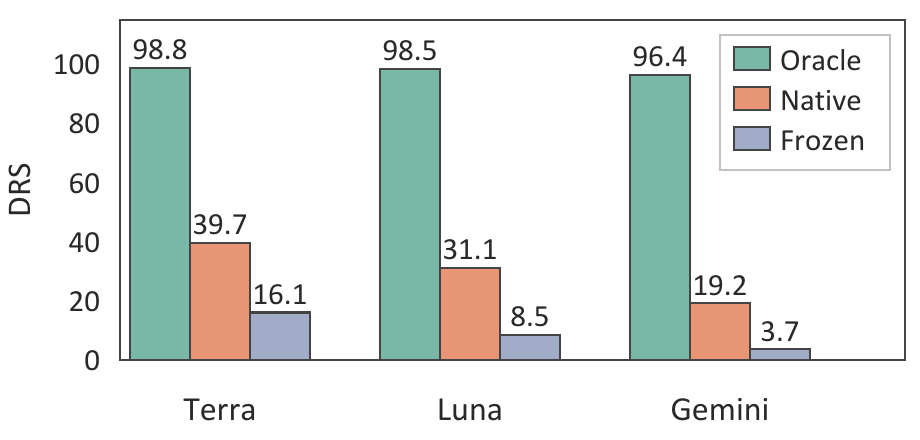
Native lets the main agent decide whether and how to revise its plan. Oracle is a reference recovery program with knowledge of the event requirements, not a capability-matched baseline. Frozen uses a continuation generated by the same model without the target result. Full-rebuild instructs the main agent to rebuild its remaining plan after each subagent result is presented, while keeping completed work. These three-agent comparisons are separate from the main experiment.Native 由主代理自行决定是否以及如何调整计划。Oracle 是知晓事件要求的参考恢复程序,不是能力匹配的基线;Frozen 使用同一模型在看不到目标结果时生成的后续动作。Full-rebuild 要求主代理在每次子代理结果呈现后重建剩余计划,同时保留已完成工作。这些针对三个智能体的对照独立于主实验。
DRS validation
Full-rebuild and Native
Community results
Approved community results are listed separately from paper results. Only result summaries are public; original evidence remains private.审核通过的社区结果独立于论文结果展示。仅结果摘要公开,原始证据始终保密。
Enable JavaScript to load community results.
Submit results提交结果
Run the benchmark and submit your results for review.运行测评,将结果提交给我们审核。
Run the benchmark运行测评
Choose the tasks and number of repetitions, run the benchmark and save the results.按需选择任务和重复次数,运行测评并保存结果。
Evaluation guide测评指南 ↗Submit privately私有提交
Follow the submission guide to prepare two files and open a pull request (PR) in your private GitHub repository.按照提交说明准备两个文件,在自己的 GitHub 私有仓库中发起拉取请求(PR)。
View the review decision查看审核结果
Read feedback in your PR. Approved result summaries sync to the community leaderboard every four hours.在 PR 中查看反馈。审核通过的结果摘要每四小时同步到社区榜单。
Citation
@misc{async_rbench,
  title = {Async-RBench: Benchmarking Asynchronous Task Execution in LLM Agents},
  author = {{Anonymous authors}},
  year = {2026},
  url = {https://github.com/pope8zdt/Async-RBench}
}